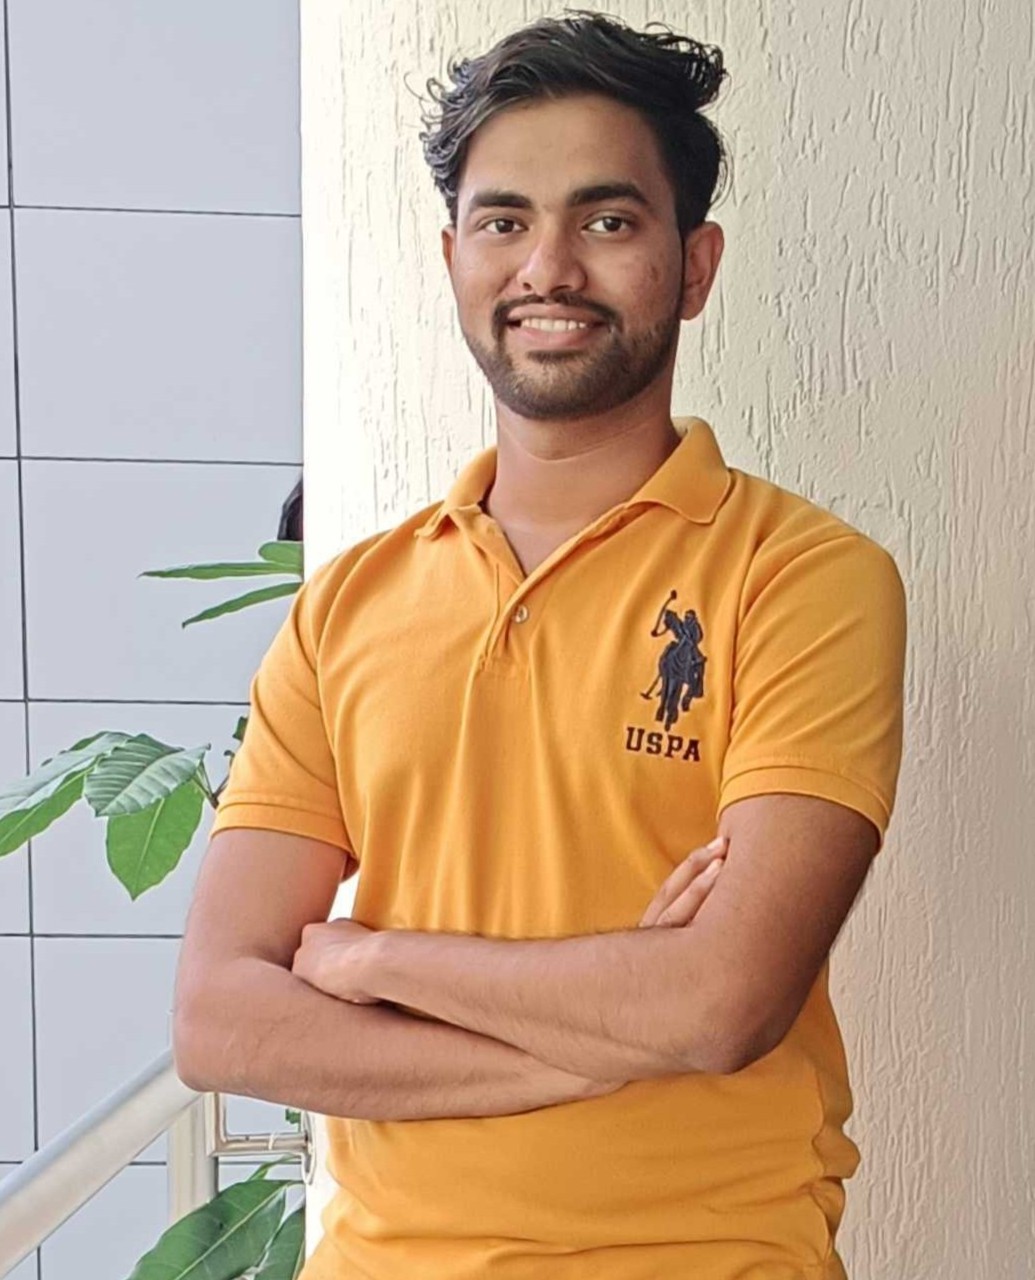
Bhushan Deshpande
I am a Data Scientist at Coriolis Technologies Pvt. Ltd. and a recent BS-MS Dual Degree graduate in Interdisciplinary Sciences (MS thesis in Data Science) from the Indian Institute of Science Education and Research (IISER), Pune. Throughout my academic journey, my work has been recognized and supported by the prestigious DST INSPIRE Fellowship and the Infosys Foundation Scholarship (2020-2025).
Academic Status: I am actively seeking PhD positions or research internships starting in the upcoming cycle within my core areas of interest or related domains.
Research Interests
My research interests lie at the intersection of Brain-Inspired AI, Computational Neuroscience, and Efficient Deep Learning. I study how biological principles—like pruning, plasticity, information bottlenecks, and inductive biases—can be formalized into architectures and learning rules to improve parameter efficiency, generalization, and representation learning in artificial neural networks.
Core Strengths & Perspectives
- Interdisciplinary Foundation: My dual degree at IISER Pune covered Data Science, Physics, Mathematics, and Biology, giving me a broad scientific perspective to approach problems creatively across fields.
- Industry & Research Experience: I have 2 years of industry experience as a Data Scientist combined with independent academic research, building skills in both fast-paced corporate and rigorous research settings.
- Leadership: Led a team of 4 engineers on RAG-based code generation at Coriolis Technologies. Supervised 2 research interns on LoRA fine-tuning Orpheus-TTS for production-quality Hindi speech synthesis.
News & Recent Updates
- October 2026: Released second arXiv preprint: DADP: Dynamic Activity-Dependent Pruning, A Reverse Hebbian-Inspired Structural Pruning Method — a biologically inspired structural sparsification algorithm evaluated across MLP, VGG-16, ResNet-18, BiLSTM-CRF, and MiniBERT architectures.
- August 2026: Open-sourced Orpheus-3B-TTS-Hindi — a LoRA fine-tuned Hindi Text-to-Speech model based on Orpheus-TTS, released on GitHub and HuggingFace.
- April 2026: Invited by the Chennai Mathematical Institute (CMI) to present two research seminars:
- Talk 1: Scalable Acquisition, Synthesis and Curation of Data for Indic LLMs (Addressing data distribution shifts between pre-training and human alignment cycles).
- Talk 2: Beyond Native Scripts: Robust Language Identification for Romanized and Code-Mixed Indian Languages (Detailing structural curriculum-based training paradigms for cross-lingual environments).
- February 2026: Participated in the International Conference on Advanced Scientific Computing & Machine Learning at BITS Pilani (Goa Campus), focusing on advanced deep learning applications and AI-driven simulations.
- November 2025: Transitioned to a full-time Data Scientist role at Coriolis Technologies Pvt. Ltd. to lead core LLM alignment engineering and high-fidelity speech architecture optimizations for Project MIRA.
- June 2025: Successfully defended my Master’s Thesis at IISER Pune: “Large-Scale Code Generation and Evaluation Using Compute-Constrained Open-Source LLMs”, graduating with an MS CGPA of 8.4.
- May 2024: Joined Coriolis Technologies Pvt. Ltd. as a Research Intern to build automated software generation and evaluation pipelines under the supervision of Mr. Sudhir Kumar.
Research & Professional Experience
- Data Scientist
Coriolis Technologies Pvt. Ltd. (Nov 2025 – Present)- LLM Alignment & Data Pipelines: Engineer data acquisition, SFT, IFT, and RLHF alignment strategies under the academic guidance of CMI and IIT Jammu faculty.
- Speech & Language Models: Built Orpheus-3B-TTS-Hindi for English-mixed Hindi speech synthesis and developed MIRA-IndicLID, a SOTA language identification model for 22 code-mixed Indian languages.
- Model Distillation: Distilled larger teacher LLMs into compact student SLMs for structured reasoning and physics problem solving.
- Master’s Thesis Researcher & Research Intern
IISER Pune & Coriolis Technologies (May 2024 – June 2025)- RAG & Self-Correction: Developed a RAG pipeline and iterative self-correction loop for complex Python scripts (600–800 lines), boosting accuracy from a 20% zero-shot baseline to 90%.
- Model Benchmarking: Evaluated instruction-following and hallucination dynamics across 12+ open-source models (1B–24B parameters) under 40 GB VRAM.
- Automated Evaluation & Deployment: Deployed an LLM-as-a-Judge framework and automated testing pipeline, reducing script development time from 2 days to under 4 hours.
Contact Info
- Email: bhushan1729dsp@gmail.com
- Profiles: GitHub LinkedIn Google Scholar Website